Upsert Entity
使用 upsert 操作可以方便地在 Collection 中插入或更新 Entity。
概述
您可以使用 upsert 操作来插入新 Entity 或更新现有 Entity,具体取决于该请求中提供的主键是否存在于 Collection 中。如果未找到主键,则执行插入操作。否则,将执行更新操作。
Zilliz Cloud 中的插入更新操作可以在覆盖或合并模式下工作。
在覆盖模式下进行 Upsert
以覆盖模式工作的插入更新请求。当收到针对现有 Entity 的 upsert 请求时,Zilliz Cloud 会插入请求负载中携带的数据,同时删除数据中指定的具有原始主键的现有 Entity。
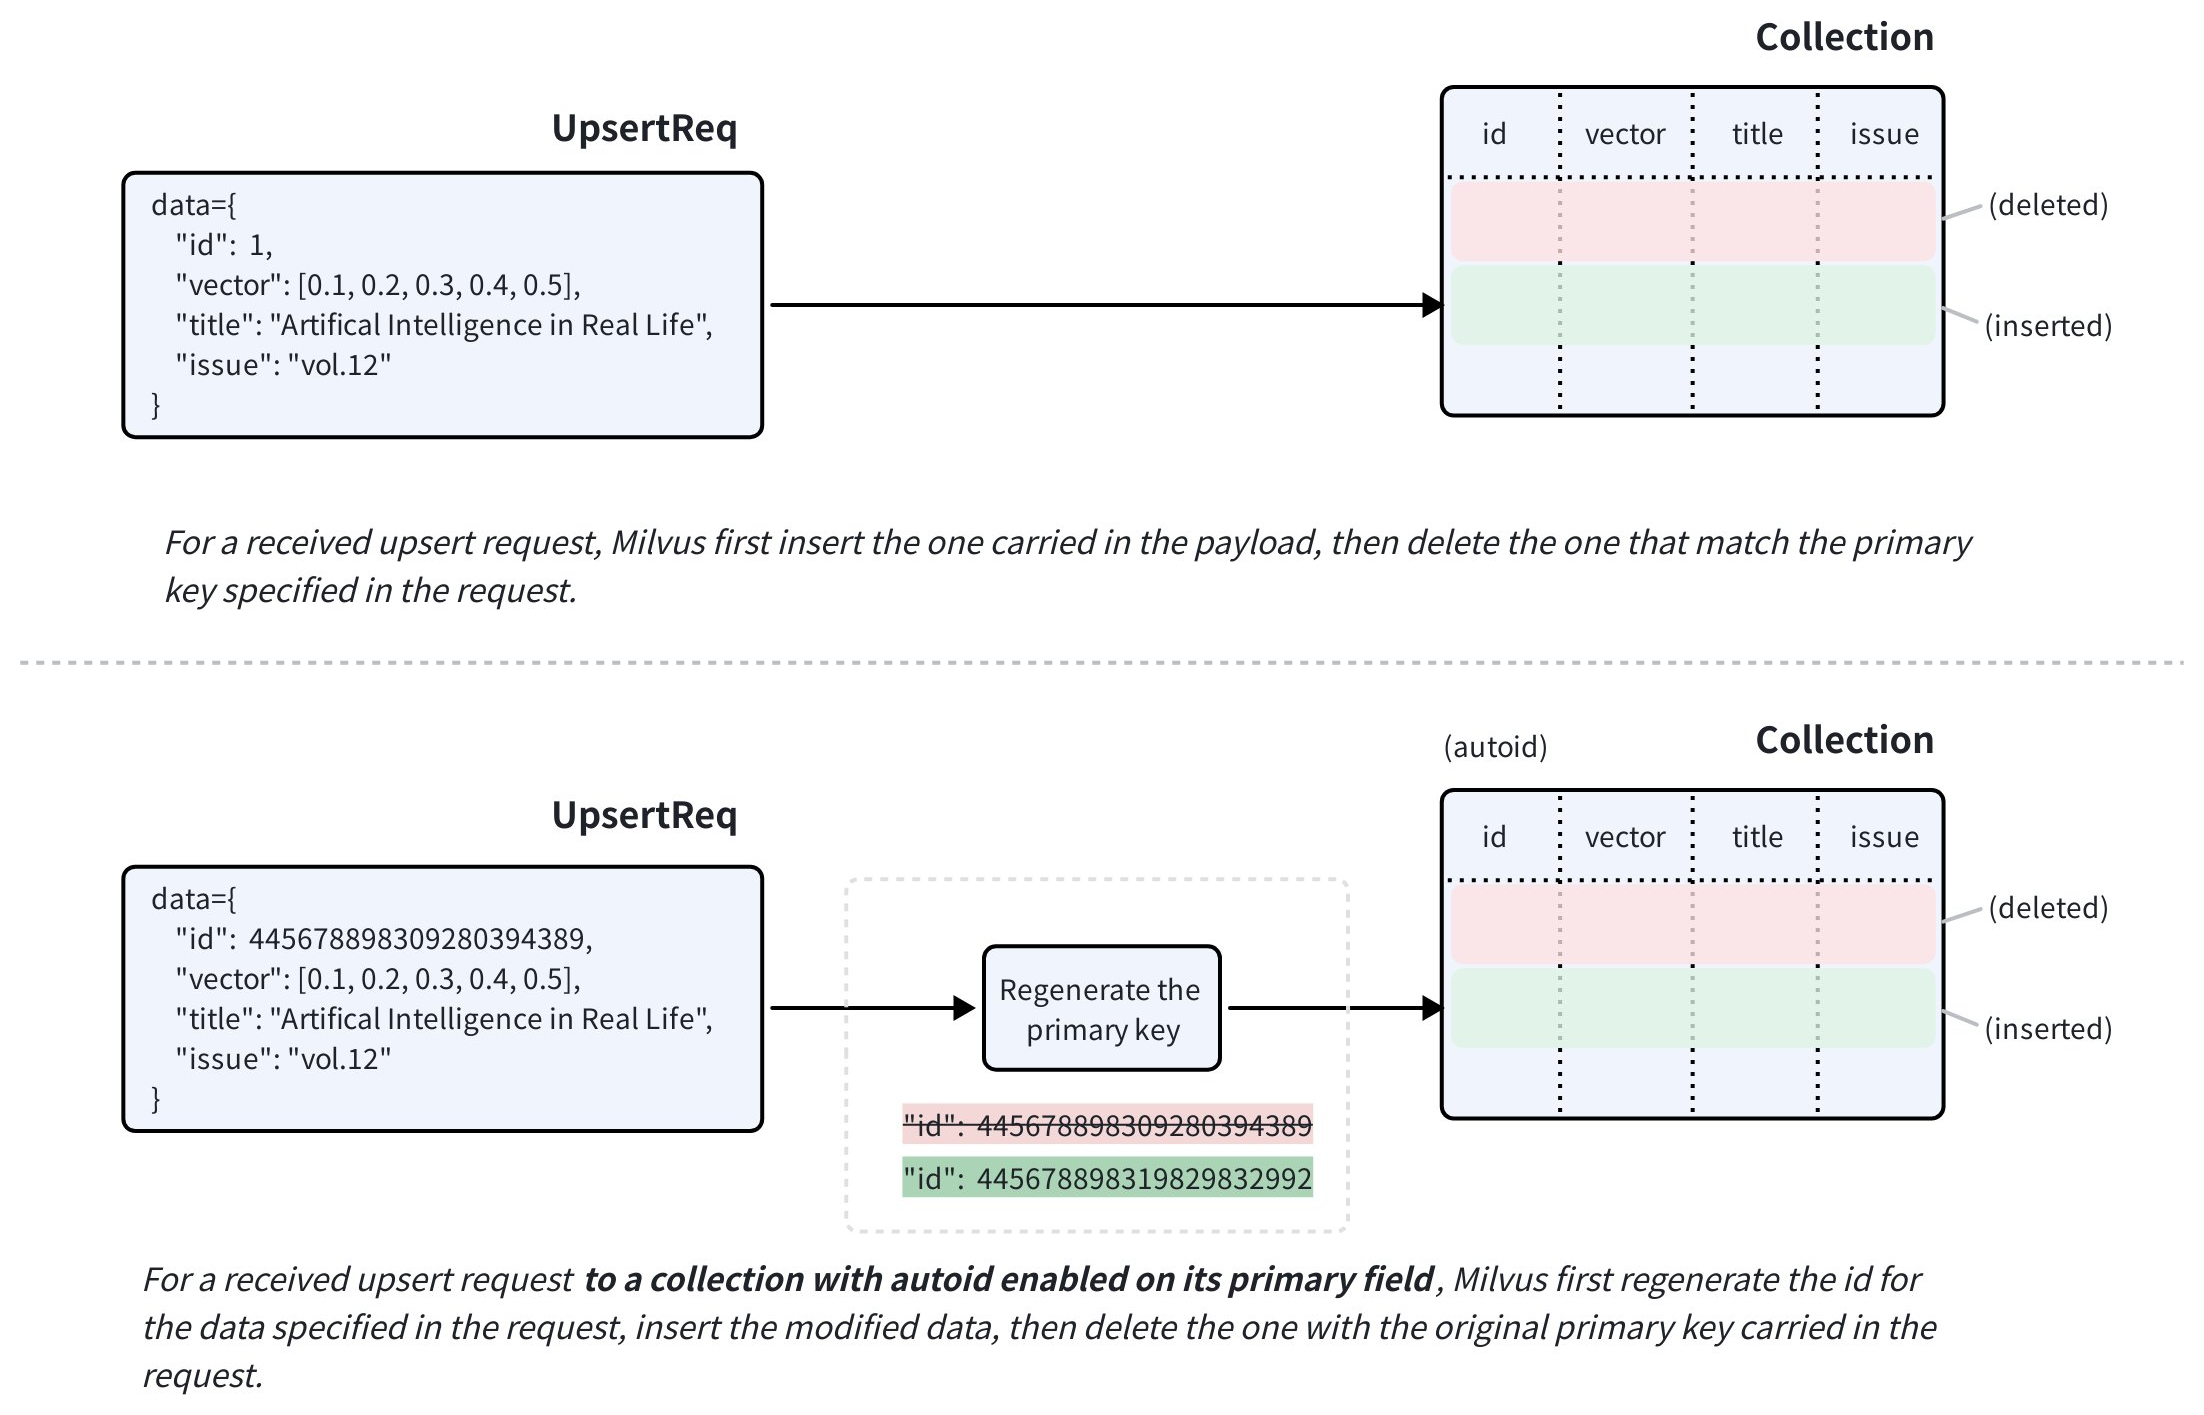
目标 Collection 的主键字段如果启用了 autoID,upsert 请求仍然必须包含目标 Entity 的主键。Zilliz Cloud 会使用请求中提供的主键定位要被替换的 Entity,并在插入前为请求负载中的新数据生成一个新的主键。
对于启用了允许为空的字段,如果不需要更新,则可以在 upsert 请求中省略它们。
在合并模式下进行 Upsert
使用合并模式可以更新已有 Entity 的指定字段,同时保留其他字段的值。
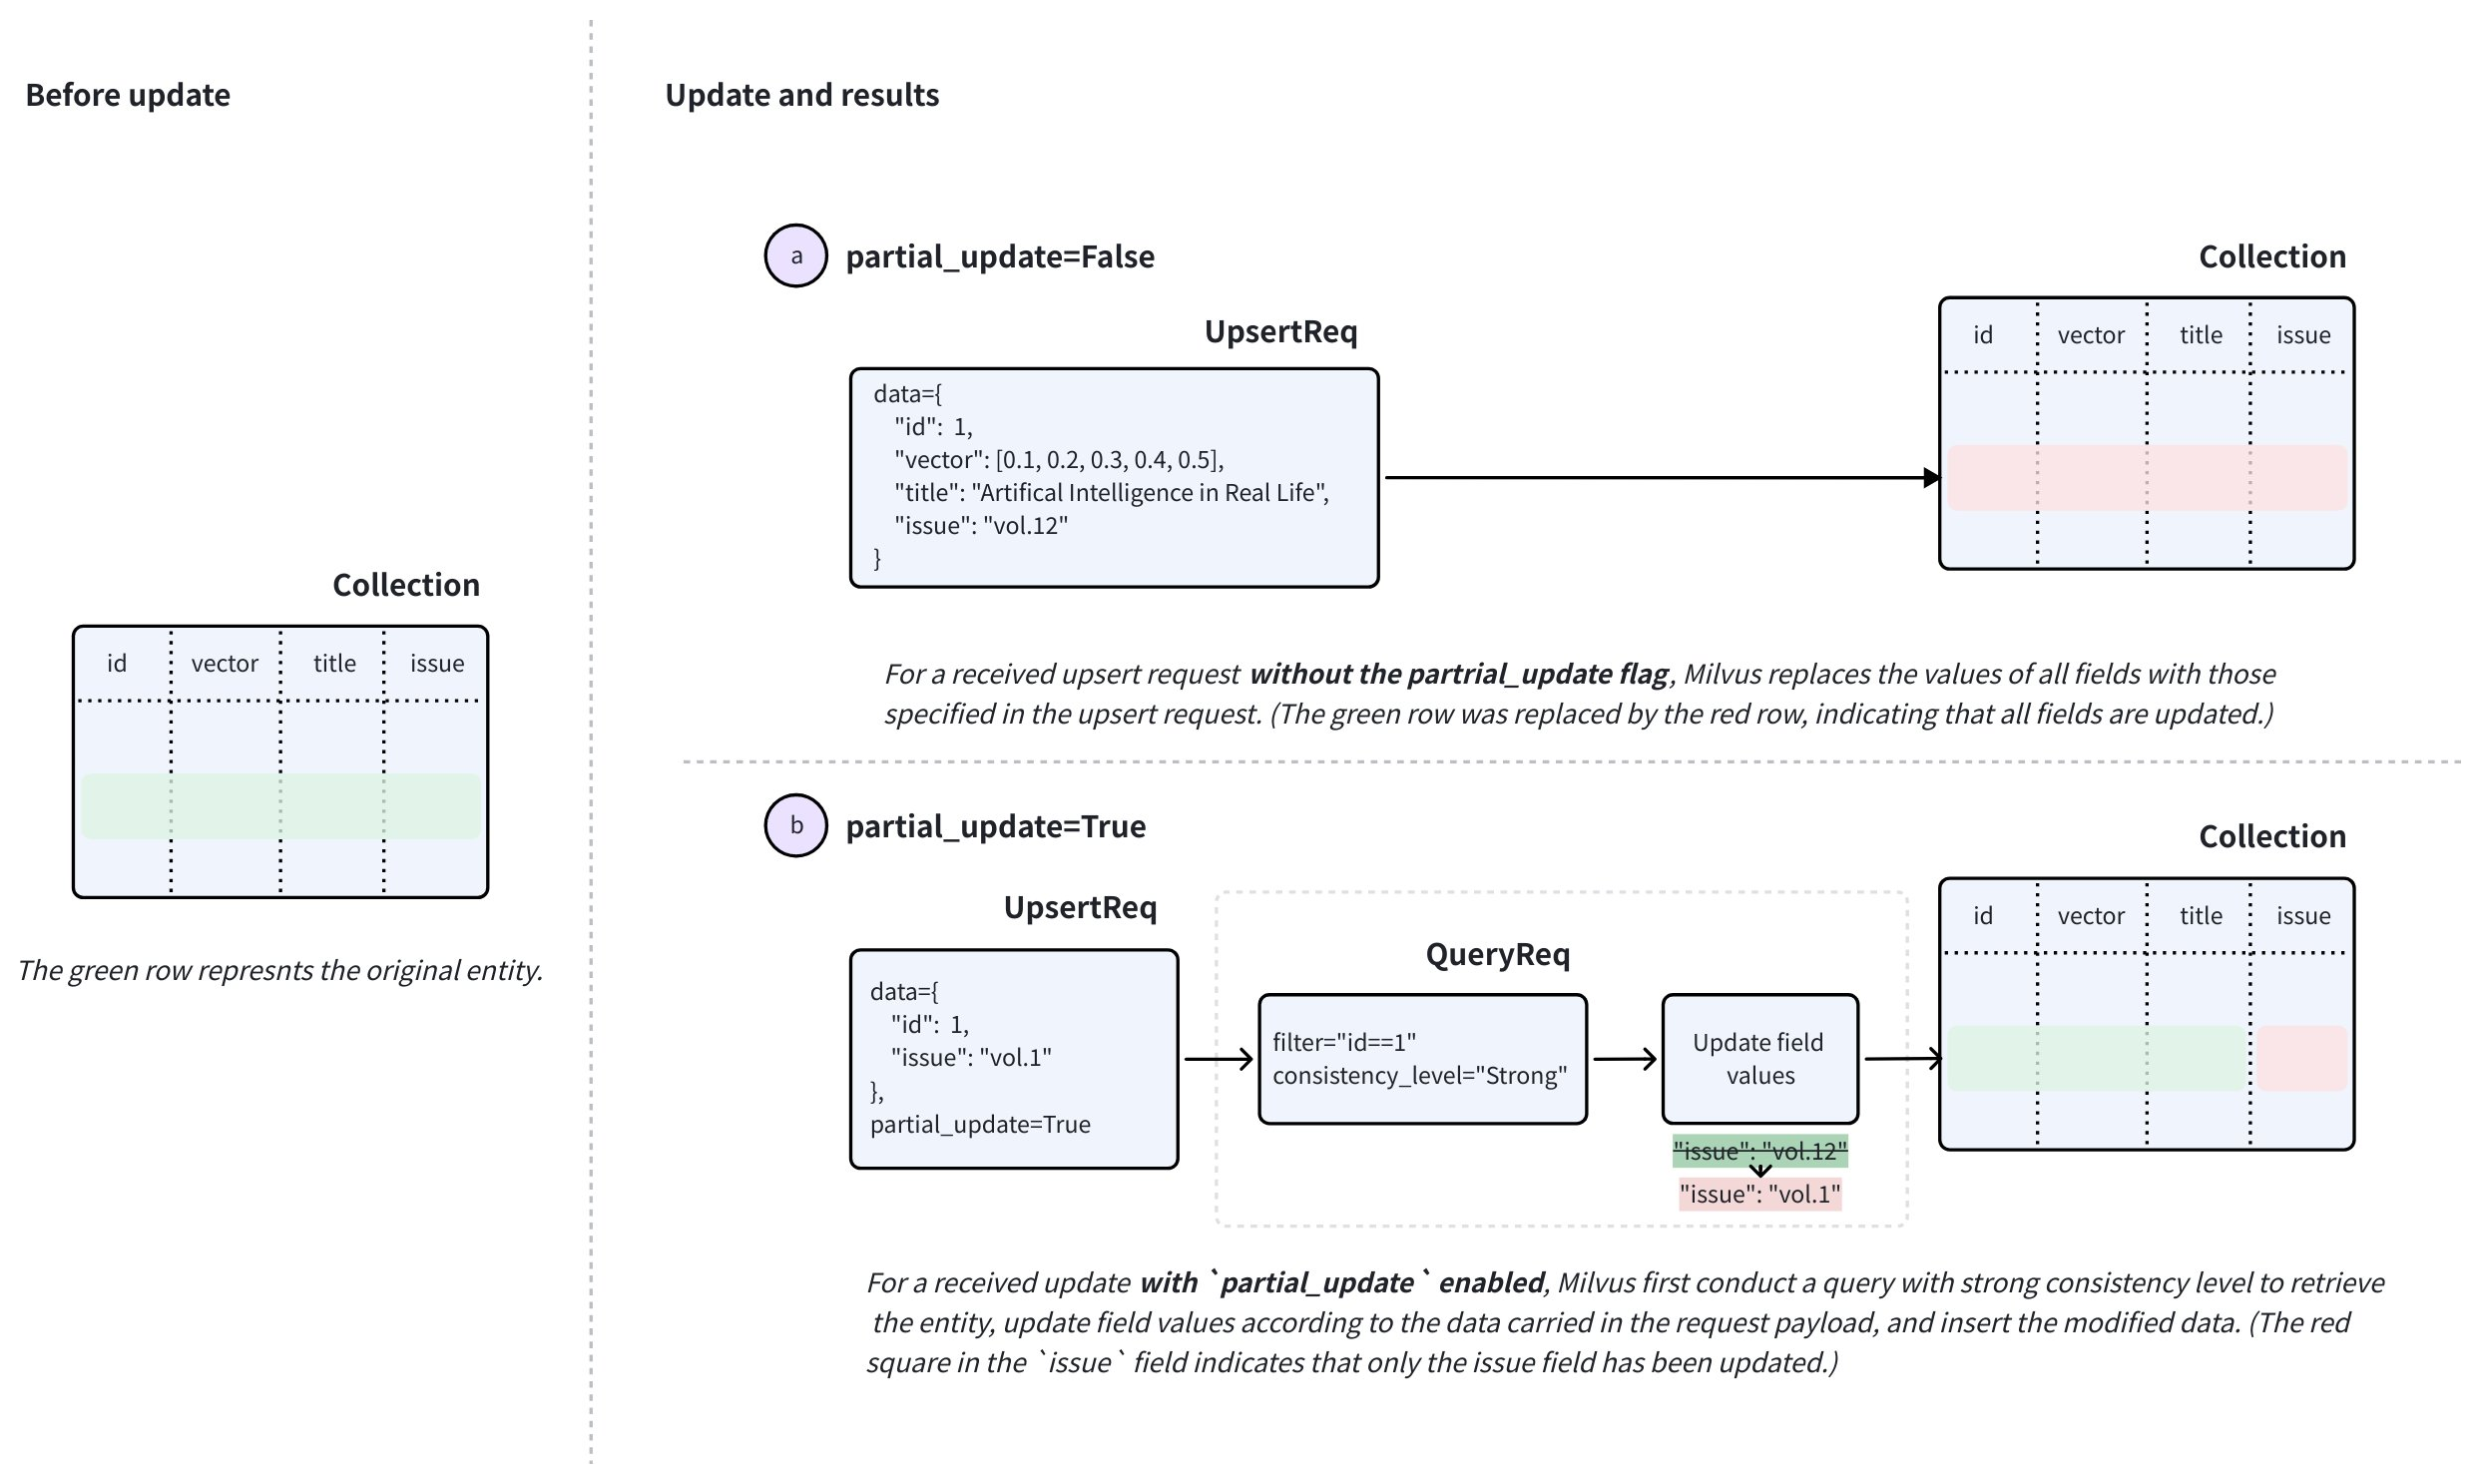
设置 partial_update=True,并提供主键以及要更新的字段。
Zilliz Cloud 会通过强一致性查询获取已有 Entity,将您提供的字段值与已有数据合并,插入合并后的 Entity,再删除旧 Entity。
在合并模式下,更新已有 Entity 时会保留其主键,即使 Collection 启用了 autoID。如果主键不存在,Zilliz Cloud 会尝试插入一个新的 Entity。插入新 Entity 时,您必须提供所有字段,否则请求会因缺少字段而失败。
如果部分更新报缺少字段的错误,请检查目标 Entity 是否存在。没有已有 Entity,系统就无法获取您在请求中省略的字段值。
创建新 Entity 时,请使用 insert 或覆盖模式下的 upsert;之后需要更新个别字段时,再使用合并模式。
对于 ARRAY 字段,合并模式还支持两个操作符:ARRAY_APPEND 和 ARRAY_REMOVE。它们允许您直接向现有 ARRAY 字段追加元素,或从现有 ARRAY 字段中移除匹配的元素,而无需先查询 Entity 来获取当前字段值。有关详细信息和代码示例,请参阅使用部分更新操作符对 ARRAY 字段执行 Upsert。
更新字段值
如需更新已有 Entity 的字段值,请使用合并模式下的 upsert 操作。在该模式下,仅请求中包含的字段会被更新,其余字段保持原值不变。
Upsert 的行为:特别说明
在使用合并功能之前,您应该考虑以下几个特别注意事项。以下情况假设您有一个 Collection,其中包含两个标量字段,分别名为标题和问题,以及一个主键id和一个名为向量的向量字段。
-
更新插入字段,允许为空已启用。
假设
issue字段可以为空。当您更新插入这些字段时,请注意:-
如果您在
upsert请求中省略issue字段并禁用partial_update,则issue字段将更新为null,而不是保留其原始值。 -
要保留
issue字段的原始值,您需要启用partial_update并省略issue字段,或者在upsert请求中包含带有其原始值的issue字段。
-
-
在 Dynamic Field 中更新插入键。
假设您已在示例 Collection 中启用 Dynamic Field,并且 Entity Dynamic Field中的键值对类似于
{"author": "John", "year": 2020, "tags": ["fiction"]}。当你使用键(如
author、year或tags)更新插入 Entity,或添加其他键时,请注意:-
如果在禁用
partial_update的情况下进行upsert操作,默认行为是覆盖。这意味着 Dynamic Field 的值将被请求中包含的所有非模式定义字段及其值覆盖。例如,如果请求中包含的数据是
{"author": "Jane", "genre": "fantasy"},则目标 Entity Dynamic Field中的键值对将更新为该数据。 -
如果在启用
partial_update的情况下进行插入或更新操作,默认行为是合并。这意味着Dynamic Field的值将与请求中包含的所有非模式定义字段及其值进行合并。例如,如果请求中包含的数据是
{"author": "John", "year": 2020, "tags": ["fiction"]},则目标 Entity Dynamic Field 中的键值对在插入更新后将变为{"author": "Jane", "year": 2020, "tags": ["fiction"], "genre": "fantasy"}。
-
-
更新插入一个 JSON 字段。
假设示例 Collection 有一个名为
extras的 JSON 字段,并且 Entity 的这个 JSON 字段中的键值对类似于{"author": "John", "year": 2020, "tags": ["fiction"]}。当您使用修改后的JSON数据更新 Entity 的
extras字段时,请注意:-
如果在禁用
partial_update的情况下进行插入或更新操作,默认行为是覆盖。这意味着请求中包含的JSON字段的值将覆盖目标 Entity 的 JSON 字段的原始值。例如,如果请求中包含的数据是
{extras: {"author": "Jane", "genre": "fantasy"}},则目标Entity 的extras字段中的键值对将更新为{"author": "Jane", "genre": "fantasy"}。 -
如果在启用
partial_update的情况下进行upsert操作,默认行为是合并。这意味着请求中包含的JSON 字段的值将与目标 Entity 的 JSON 字段的原始值合并。例如,如果请求中包含的数据是
{extras: {"author": "Jane", "genre": "fantasy"}},则更新后目标 Entity 的extras字段中的键值对将变为{"author": "Jane", "year": 2020, "tags": ["fiction"], "genre": "fantasy"}。
-
-
Upsert
ARRAY字段。默认情况下,
ARRAY字段在合并模式下遵循 REPLACE 语义:请求中携带的值会完整覆盖现有数组。如需进行更细粒度的更新,Milvus 还支持两个操作符:-
ARRAY_APPEND将请求载荷中的元素追加到现有数组中。 -
ARRAY_REMOVE从现有数组中移除与请求载荷中的值匹配的所有元素。
使用任一操作符都会隐式启用部分更新语义;您无需额外将
partial_update设置为True。有关操作符语法、支持的元素类型和其他限制,请参阅使用部分更新操作符对 ARRAY 字段执行 Upsert。 -
限制与约束
根据上述内容,有若干限制和约束需要遵循:
-
upsert请求必须始终包含目标 Entity 的主键,即使启用了autoID。对于启用autoID的 Collection,主键的处理方式取决于 upsert 模式:-
在覆盖模式下,主键标识要被替换的已有 Entity,Zilliz Cloud 会为替换后的 Entity 生成一个新的主键。
-
在合并模式下,更新已有 Entity 时会保留其主键。如果主键不存在,Zilliz Cloud 会尝试插入一个新的 Entity。插入新 Entity 时,您必须提供所有字段,否则请求会因缺少字段而失败。
-
-
目标 Collection 必须已加载且可用于查询。
-
请求中指定的所有字段必须存在于目标 Collection 的 Schema 中。
-
请求中指定的所有字段的值必须与 Schema 中定义的数据类型相匹配。
-
对于任何使用 Function 从其他字段派生而来的字段,Zilliz Cloud 将在
upsert期间移除派生字段,以便重新计算。
在 Collection 中 Upsert Entity
在本节中,我们将向名为my_collection的 Collection 中 Upsert Entity 。这个 Collection 只有两个字段,分别名为id、vector、title和issue。id字段是主键字段,而title和issue字段是标量字段。
如果 Collection 中存在这三个实体,它们将被包含在更新插入请求中的实体覆盖。
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
from pymilvus import MilvusClient

client = MilvusClient(
    uri="YOUR_CLUSTER_ENDPOINT",
    token="YOUR_CLUSTER_TOKEN"
)

data=[
    {
        "id": 0,
        "vector": [-0.619954382375778, 0.4479436794798608, -0.17493894838751745, -0.4248030059917294, -0.8648452746018911],
        "title": "Artificial Intelligence in Real Life",
        "issue": "vol.12"
    }, {
        "id": 1,
        "vector": [0.4762662251462588, -0.6942502138717026, -0.4490002642657902, -0.628696575798281, 0.9660395877041965],
        "title": "Hollow Man",
        "issue": "vol.19"
    }, {
        "id": 2,
        "vector": [-0.8864122635045097, 0.9260170474445351, 0.801326976181461, 0.6383943392381306, 0.7563037341572827],
        "title": "Treasure Hunt in Missouri",
        "issue": "vol.12"
    }
]

res = client.upsert(
    collection_name='my_collection',
    data=data
)

print(res)

# Output
# {'upsert_count': 3}
import com.google.gson.Gson;
import com.google.gson.JsonObject;
import io.milvus.v2.client.ConnectConfig;
import io.milvus.v2.client.MilvusClientV2;
import io.milvus.v2.service.vector.request.UpsertReq;
import io.milvus.v2.service.vector.response.UpsertResp;
import java.util.*;

MilvusClientV2 client = new MilvusClientV2(ConnectConfig.builder()

        .uri("YOUR_CLUSTER_ENDPOINT")

        .token("YOUR_CLUSTER_TOKEN")

        .build());

Gson gson = new Gson();

List<JsonObject> data = Arrays.asList(

        gson.fromJson("{\"id\": 0, \"vector\": [-0.619954382375778, 0.4479436794798608, -0.17493894838751745, -0.4248030059917294, -0.8648452746018911], \"title\": \"Artificial Intelligence in Real Life\", \"issue\": \"vol.12\"}", JsonObject.class),
        gson.fromJson("{\"id\": 1, \"vector\": [0.4762662251462588, -0.6942502138717026, -0.4490002642657902, -0.628696575798281, 0.9660395877041965], \"title\": \"Hollow Man\", \"issue\": \"vol.19\"}", JsonObject.class),
        gson.fromJson("{\"id\": 2, \"vector\": [-0.8864122635045097, 0.9260170474445351, 0.801326976181461, 0.6383943392381306, 0.7563037341572827], \"title\": \"Treasure Hunt in Missouri\", \"issue\": \"vol.12\"}", JsonObject.class)
);

UpsertReq upsertReq = UpsertReq.builder()

        .collectionName("my_collection")

        .data(data)

        .build();

UpsertResp upsertResp = client.upsert(upsertReq);

System.out.println(upsertResp);

// Output:

//

// UpsertResp(upsertCnt=3)
import (
    "context"
    "fmt"

    "github.com/milvus-io/milvus/client/v3/column"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx := context.Background()

milvusAddr := "YOUR_CLUSTER_ENDPOINT"

client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
})

if err != nil {
    fmt.Println(err.Error())

    // handle error
}

defer client.Close(ctx)

titleColumn := column.NewColumnVarChar("title", []string{
    "Artificial Intelligence in Real Life", "Hollow Man", "Treasure Hunt in Missouri",
})

issueColumn := column.NewColumnVarChar("issue", []string{
    "vol.12", "vol.19", "vol.12",
})

_, err = client.Upsert(ctx, milvusclient.NewColumnBasedInsertOption("my_collection").

    WithInt64Column("id", []int64{0, 1, 2}).

    WithFloatVectorColumn("vector", 5, [][]float32{
        {-0.619954382375778, 0.4479436794798608, -0.17493894838751745, -0.4248030059917294, -0.8648452746018911},
        {0.4762662251462588, -0.6942502138717026, -0.4490002642657902, -0.628696575798281, 0.9660395877041965},
        {-0.8864122635045097, 0.9260170474445351, 0.801326976181461, 0.6383943392381306, 0.7563037341572827},
    }).

    WithColumns(titleColumn, issueColumn),
)

if err != nil {
    fmt.Println(err.Error())

    // handle err
}
use milvus::v2::prelude::*;

let config = ConnectConfig::new().uri("YOUR_CLUSTER_ENDPOINT").token("YOUR_CLUSTER_TOKEN");

let client = ClientV2::new(&config).await?;

client

    .upsert(

        UpsertRequest::builder()

            .insert(

                InsertRequest::builder()

                    .collection_name("my_collection")

                    .columns(vec![

                        FieldData::Int64 {
                            name: "id".into(),
                            values: vec![0i64, 1, 2],
                        },
                        FieldData::FloatVector {
                            name: "vector".into(),
                            values: vec![
                                vec![-0.619954382375778, 0.4479436794798608, -0.17493894838751745, -0.4248030059917294, -0.8648452746018911],
                                vec![0.4762662251462588, -0.6942502138717026, -0.4490002642657902, -0.628696575798281, 0.9660395877041965],
                                vec![-0.8864122635045097, 0.9260170474445351, 0.801326976181461, 0.6383943392381306, 0.7563037341572827],
                            ],
                        },
                        FieldData::VarChar {
                            name: "title".into(),
                            values: vec![
                                "Artificial Intelligence in Real Life".into(),
                                "Hollow Man".into(),
                                "Treasure Hunt in Missouri".into(),
                            ],
                        },
                        FieldData::VarChar {
                            name: "issue".into(),
                            values: vec!["vol.12".into(), "vol.19".into(), "vol.12".into()],
                        },
                    ])

                    .build()?,
            )

            .build()?,
    )

    .await?;
#include "milvus/MilvusClientV2.h"

auto client = milvus::MilvusClientV2::Create();

milvus::ConnectParam connect_param{"YOUR_CLUSTER_ENDPOINT", "YOUR_CLUSTER_TOKEN"};
auto status = client->Connect(connect_param);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

milvus::EntityRows data = {
    {{"id", 0}, {"vector", std::vector<float>{-0.619954382375778, 0.4479436794798608, -0.17493894838751745, -0.4248030059917294, -0.8648452746018911}}, {"title", "Artificial Intelligence in Real Life"}, {"issue", "vol.12"}},
    {{"id", 1}, {"vector", std::vector<float>{0.4762662251462588, -0.6942502138717026, -0.4490002642657902, -0.628696575798281, 0.9660395877041965}}, {"title", "Hollow Man"}, {"issue", "vol.19"}},
    {{"id", 2}, {"vector", std::vector<float>{-0.8864122635045097, 0.9260170474445351, 0.801326976181461, 0.6383943392381306, 0.7563037341572827}}, {"title", "Treasure Hunt in Missouri"}, {"issue", "vol.12"}}
};

milvus::UpsertResponse resp_upsert;
status = client->Upsert(milvus::UpsertRequest()
                            .WithCollectionName("my_collection")
                            .WithRowsData(std::move(data)),
                        resp_upsert);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
import { MilvusClient, DataType } from "@zilliz/milvus2-sdk-node";

const address = "YOUR_CLUSTER_ENDPOINT";
const token = "YOUR_CLUSTER_TOKEN";
const client = new MilvusClient({address, token});

const data = [
    {id: 0, vector: [-0.619954382375778, 0.4479436794798608, -0.17493894838751745, -0.4248030059917294, -0.8648452746018911], title: "Artificial Intelligence in Real Life", issue: "vol.12"},
    {id: 1, vector: [0.4762662251462588, -0.6942502138717026, -0.4490002642657902, -0.628696575798281, 0.9660395877041965], title: "Hollow Man", issue: "vol.19"},
    {id: 2, vector: [-0.8864122635045097, 0.9260170474445351, 0.801326976181461, 0.6383943392381306, 0.7563037341572827], title: "Treasure Hunt in Missouri", issue: "vol.12"},
]

const res = await client.upsert({
    collection_name: "my_collection",
    data: data,
})

console.log(res.upsert_cnt)

// Output
//
// 3
//
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"

export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \

--url "${CLUSTER_ENDPOINT}/v2/vectordb/entities/upsert" \

--header "Authorization: Bearer ${TOKEN}" \

--header "Content-Type: application/json" \

--header "Request-Timeout: 10" \

-d '{
    "data": [
        {"id": 0, "vector": [-0.619954382375778, 0.4479436794798608, -0.17493894838751745, -0.4248030059917294, -0.8648452746018911], "title": "Artificial Intelligence in Real Life", "issue": "vol.12"},
        {"id": 1, "vector": [0.4762662251462588, -0.6942502138717026, -0.4490002642657902, -0.628696575798281, 0.9660395877041965], "title": "Hollow Man", "issue": "vol.19"},
        {"id": 2, "vector": [-0.8864122635045097, 0.9260170474445351, 0.801326976181461, 0.6383943392381306, 0.7563037341572827], "title": "Treasure Hunt in Missouri", "issue": "vol.12"}
    ],
    "collectionName": "my_collection"
}'

# {
#     "code": 0,
#     "data": {
#         "upsertCount": 3,
#         "upsertIds": [
#             0,
#             1,
#             2,
#         ]
#     }
# }
在 Partition 中 Upsert Entity
您还可以将 Entity Upsert 到指定 Partition 中。以下代码片段假定您的 Collection 中有一个名为 PartitionA 的 Partition。
如果 Partition 中存在这三个 Entity,它们将被请求中包含的 Entity 覆盖。
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
data=[
    {
        "id": 10,
        "vector": [0.06998888224297328, 0.8582816610326578, -0.9657938677934292, 0.6527905683627726, -0.8668460657158576],
        "title": "Layour Design Reference",
        "issue": "vol.34"
    },
    {
        "id": 11,
        "vector": [0.6060703043917468, -0.3765080534566074, -0.7710758854987239, 0.36993888322346136, 0.5507513364206531],
        "title": "Doraemon and His Friends",
        "issue": "vol.2"
    },
    {
        "id": 12,
        "vector": [-0.9041813104515337, -0.9610546012461163, 0.20033003106083358, 0.11842506351635174, 0.8327356724591011],
        "title": "Pikkachu and Pokemon",
        "issue": "vol.12"
    },
]

res = client.upsert(
    collection_name="my_collection",
    data=data,
    partition_name="partitionA"
)

print(res)

# Output
# {'upsert_count': 3}
import com.google.gson.Gson;
import com.google.gson.JsonObject;
import io.milvus.v2.service.vector.request.UpsertReq;
import io.milvus.v2.service.vector.response.UpsertResp;
import java.util.Arrays;
import java.util.List;

Gson gson = new Gson();

List<JsonObject> data = Arrays.asList(

        gson.fromJson("{\"id\": 10, \"vector\": [0.06998888224297328, 0.8582816610326578, -0.9657938677934292, 0.6527905683627726, -0.8668460657158576], \"title\": \"Layour Design Reference\", \"issue\": \"vol.34\"}", JsonObject.class),
        gson.fromJson("{\"id\": 11, \"vector\": [0.6060703043917468, -0.3765080534566074, -0.7710758854987239, 0.36993888322346136, 0.5507513364206531], \"title\": \"Doraemon and His Friends\", \"issue\": \"vol.2\"}", JsonObject.class),
        gson.fromJson("{\"id\": 12, \"vector\": [-0.9041813104515337, -0.9610546012461163, 0.20033003106083358, 0.11842506351635174, 0.8327356724591011], \"title\": \"Pikkachu and Pokemon\", \"issue\": \"vol.12\"}", JsonObject.class)
);

UpsertReq upsertReq = UpsertReq.builder()

        .collectionName("my_collection")

        .partitionName("partitionA")

        .data(data)

        .build();

UpsertResp upsertResp = client.upsert(upsertReq);

System.out.println(upsertResp);

// Output:

//

// UpsertResp(upsertCnt=3)
import (
    "context"
    "fmt"

    "github.com/milvus-io/milvus/client/v3/column"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx := context.Background()

milvusAddr := "YOUR_CLUSTER_ENDPOINT"

client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
})

if err != nil {
    fmt.Println(err.Error())

    // handle error
}

defer client.Close(ctx)

titleColumn := column.NewColumnVarChar("title", []string{
    "Layour Design Reference", "Doraemon and His Friends", "Pikkachu and Pokemon",
})

issueColumn := column.NewColumnVarChar("issue", []string{
    "vol.34", "vol.2", "vol.12",
})

_, err = client.Upsert(ctx, milvusclient.NewColumnBasedInsertOption("my_collection").

    WithPartition("partitionA").

    WithInt64Column("id", []int64{10, 11, 12}).

    WithFloatVectorColumn("vector", 5, [][]float32{
        {0.06998888224297328, 0.8582816610326578, -0.9657938677934292, 0.6527905683627726, -0.8668460657158576},
        {0.6060703043917468, -0.3765080534566074, -0.7710758854987239, 0.36993888322346136, 0.5507513364206531},
        {-0.9041813104515337, -0.9610546012461163, 0.20033003106083358, 0.11842506351635174, 0.8327356724591011},
    }).

    WithColumns(titleColumn, issueColumn),
)

if err != nil {
    fmt.Println(err.Error())

    // handle err
}
use milvus::v2::prelude::*;

let config = ConnectConfig::new().uri("YOUR_CLUSTER_ENDPOINT").token("YOUR_CLUSTER_TOKEN");

let client = ClientV2::new(&config).await?;

client

    .upsert(

        UpsertRequest::builder()

            .insert(

                InsertRequest::builder()

                    .collection_name("my_collection")

                    .partition_name("partitionA")

                    .columns(vec![

                        FieldData::Int64 {
                            name: "id".into(),
                            values: vec![10i64, 11, 12],
                        },
                        FieldData::FloatVector {
                            name: "vector".into(),
                            values: vec![
                                vec![0.06998888224297328, 0.8582816610326578, -0.9657938677934292, 0.6527905683627726, -0.8668460657158576],
                                vec![0.6060703043917468, -0.3765080534566074, -0.7710758854987239, 0.36993888322346136, 0.5507513364206531],
                                vec![-0.9041813104515337, -0.9610546012461163, 0.20033003106083358, 0.11842506351635174, 0.8327356724591011],
                            ],
                        },
                        FieldData::VarChar {
                            name: "title".into(),
                            values: vec![
                                "Layour Design Reference".into(),
                                "Doraemon and His Friends".into(),
                                "Pikkachu and Pokemon".into(),
                            ],
                        },
                        FieldData::VarChar {
                            name: "issue".into(),
                            values: vec!["vol.34".into(), "vol.2".into(), "vol.12".into()],
                        },
                    ])

                    .build()?,
            )

            .build()?,
    )

    .await?;
#include <iostream>
#include "milvus/MilvusClientV2.h"

auto client = milvus::MilvusClientV2::Create();

milvus::ConnectParam connect_param{"YOUR_CLUSTER_ENDPOINT", "YOUR_CLUSTER_TOKEN"};

auto status = client->Connect(connect_param);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

milvus::EntityRows data = {
    {{"id", 10}, {"vector", std::vector<float>{0.06998888224297328, 0.8582816610326578, -0.9657938677934292, 0.6527905683627726, -0.8668460657158576}}, {"title", "Layour Design Reference"}, {"issue", "vol.34"}},
    {{"id", 11}, {"vector", std::vector<float>{0.6060703043917468, -0.3765080534566074, -0.7710758854987239, 0.36993888322346136, 0.5507513364206531}}, {"title", "Doraemon and His Friends"}, {"issue", "vol.2"}},
    {{"id", 12}, {"vector", std::vector<float>{-0.9041813104515337, -0.9610546012461163, 0.20033003106083358, 0.11842506351635174, 0.8327356724591011}}, {"title", "Pikkachu and Pokemon"}, {"issue", "vol.12"}}
};

milvus::UpsertResponse resp_upsert;

status = client->Upsert(milvus::UpsertRequest()

                            .WithCollectionName("my_collection")

                            .WithPartitionName("partitionA")

                            .WithRowsData(std::move(data)),
                        resp_upsert);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
import { MilvusClient, DataType } from "@zilliz/milvus2-sdk-node";

// 6. Upsert data in partitions
const data = [
    {id: 10, vector: [0.06998888224297328, 0.8582816610326578, -0.9657938677934292, 0.6527905683627726, -0.8668460657158576], title: "Layour Design Reference", issue: "vol.34"},
    {id: 11, vector: [0.6060703043917468, -0.3765080534566074, -0.7710758854987239, 0.36993888322346136, 0.5507513364206531], title: "Doraemon and His Friends", issue: "vol.2"},
    {id: 12, vector: [-0.9041813104515337, -0.9610546012461163, 0.20033003106083358, 0.11842506351635174, 0.8327356724591011], title: "Pikkachu and Pokemon", issue: "vol.12"},
]

const res = await client.upsert({
    collection_name: "my_collection",
    data: data,
    partition_name: "partitionA"
})

console.log(res.upsert_cnt)

// Output
//
// 3
//
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"

export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \

--url "${CLUSTER_ENDPOINT}/v2/vectordb/entities/upsert" \

--header "Authorization: Bearer ${TOKEN}" \

--header "Content-Type: application/json" \

--header "Request-Timeout: 10" \

-d '{
    "data": [
        {"id": 10, "vector": [0.06998888224297328, 0.8582816610326578, -0.9657938677934292, 0.6527905683627726, -0.8668460657158576], "title": "Layour Design Reference", "issue": "vol.34"},
        {"id": 11, "vector": [0.6060703043917468, -0.3765080534566074, -0.7710758854987239, 0.36993888322346136, 0.5507513364206531], "title": "Doraemon and His Friends", "issue": "vol.2"},
        {"id": 12, "vector": [-0.9041813104515337, -0.9610546012461163, 0.20033003106083358, 0.11842506351635174, 0.8327356724591011], "title": "Pikkachu and Pokemon", "issue": "vol.12"}
    ],
    "collectionName": "my_collection",
    "partitionName": "partitionA"
}'

# {
#     "code": 0,
#     "data": {
#         "upsertCount": 3,
#         "upsertIds": [
#             10,
#             11,
#             12,
#         ]
#     }
# }
在合并模式下 Upsert Entity
以下示例仅更新 my_collection 中主键为 1 和 2 的 Entity 的 issue 字段。运行前,请确保这两个 Entity 已存在。它们的其他字段会保留原值。
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
data=[
    {
        "id": 1,
        "issue": "vol.14"
    },
    {
        "id": 2,
        "issue": "vol.7"
    }
]

res = client.upsert(
    collection_name="my_collection",
    data=data,
    partial_update=True
)

print(res)

# Output
# {'upsert_count': 2}
import com.google.gson.JsonObject;
import io.milvus.v2.service.vector.request.UpsertReq;
import io.milvus.v2.service.vector.response.UpsertResp;
import java.util.Arrays;

JsonObject row1 = new JsonObject();

row1.addProperty("id", 1);

row1.addProperty("issue", "vol.14");

JsonObject row2 = new JsonObject();

row2.addProperty("id", 2);

row2.addProperty("issue", "vol.7");

UpsertReq upsertReq = UpsertReq.builder()

        .collectionName("my_collection")

        .data(Arrays.asList(row1, row2))

        .partialUpdate(true)

        .build();

UpsertResp upsertResp = client.upsert(upsertReq);

System.out.println(upsertResp);

// Output:

//

// UpsertResp(upsertCnt=2)
import (
    "context"
    "fmt"

    "github.com/milvus-io/milvus/client/v3/column"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx := context.Background()

milvusAddr := "YOUR_CLUSTER_ENDPOINT"

client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
})

if err != nil {
    fmt.Println(err.Error())

    // handle error
}

defer client.Close(ctx)

pkColumn := column.NewColumnInt64("id", []int64{1, 2})

issueColumn := column.NewColumnVarChar("issue", []string{
    "vol.14", "vol.7",
})

_, err = client.Upsert(ctx, milvusclient.NewColumnBasedInsertOption("my_collection").

    WithColumns(pkColumn, issueColumn).

    WithPartialUpdate(true),
)

if err != nil {
    fmt.Println(err.Error())

    // handle err
}
use milvus::v2::prelude::*;

let config = ConnectConfig::new().uri("YOUR_CLUSTER_ENDPOINT").token("YOUR_CLUSTER_TOKEN");

let client = ClientV2::new(&config).await?;

client

    .upsert(

        UpsertRequest::builder()

            .insert(

                InsertRequest::builder()

                    .collection_name("my_collection")

                    .columns(vec![

                        FieldData::Int64 {
                            name: "id".into(),
                            values: vec![1i64, 2],
                        },
                        FieldData::VarChar {
                            name: "issue".into(),
                            values: vec!["vol.14".into(), "vol.7".into()],
                        },
                    ])

                    .build()?,
            )

            .partial_update(true)

            .build()?,
    )

    .await?;
#include <iostream>
#include "milvus/MilvusClientV2.h"

auto client = milvus::MilvusClientV2::Create();

milvus::ConnectParam connect_param{"YOUR_CLUSTER_ENDPOINT", "YOUR_CLUSTER_TOKEN"};

auto status = client->Connect(connect_param);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

milvus::EntityRows data = {{{"id", 1}, {"issue", "vol.14"}},
                           {{"id", 2}, {"issue", "vol.7"}}};

milvus::UpsertResponse resp_upsert;

status = client->Upsert(milvus::UpsertRequest()

                            .WithCollectionName("my_collection")

                            .WithRowsData(std::move(data))

                            .WithPartialUpdate(true),
                        resp_upsert);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
const data=[
    {
        "id": 1,
        "issue": "vol.14"
    },
    {
        "id": 2,
        "issue": "vol.7"
    }
];

const res = await client.upsert({
    collection_name: "my_collection",
    data,
    partial_update: true
});

console.log(res)

// Output
//
// 2
//
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"
export TOKEN="YOUR_CLUSTER_TOKEN"

export COLLECTION_NAME="my_collection"
export UPSERT_DATA='[
  {
    "id": 1,
    "issue": "vol.14"
  },
  {
    "id": 2,
    "issue": "vol.7"
  }
]'

curl -X POST "YOUR_CLUSTER_ENDPOINT/v2/vectordb/entities/upsert" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer ${TOKEN}" \
  -H "Request-Timeout: 10" \
  -d "{
    \"collectionName\": \"${COLLECTION_NAME}\",
    \"data\": ${UPSERT_DATA},
    \"partialUpdate\": true
  }"

# {
#     "code": 0,
#     "data": {
#         "upsertCount": 2,
#         "upsertIds": [
#              3,
#             12,
#         ]
#     }
# }
使用部分更新操作符对 ARRAY 字段执行 Upsert
在引入部分更新操作符(ARRAY_APPEND 和 ARRAY_REMOVE)之前,如果您需要更新 ARRAY 字段中的部分元素,通常需要在客户端执行读取-修改-写入流程:先查询现有数组,在应用代码中修改数组,然后通过 Upsert 写入完整的新数组。部分更新操作符允许您只发送需要追加或移除的元素,从而减少客户端逻辑,并避免在 Upsert 前额外查询一次现有数组。
假设主键为 1 的 Entity 已有 tags = ["new", "trial"]。在没有部分更新操作符时,添加数组元素 "premium" 需要 Upsert 完整的新数组:
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
client.upsert(
    collection_name="users",
    data=[{"pk": 1, "tags": ["new", "trial", "premium"]}],
    partial_update=True,
)
import com.google.gson.JsonObject;
import io.milvus.v2.service.vector.request.UpsertReq;
import java.util.Collections;
import java.util.List;
import com.google.gson.Gson;

Gson gson = new Gson();

List<JsonObject> replacementData = Collections.singletonList(

        gson.fromJson("{\"pk\": 1, \"tags\": [\"new\", \"trial\", \"premium\"]}", JsonObject.class)
);

client.upsert(UpsertReq.builder()

        .collectionName("users")


        .partialUpdate(true)

        .data(replacementData)


        .build());
import (
    "context"
    "fmt"

    "github.com/milvus-io/milvus/client/v3/column"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx := context.Background()

milvusAddr := "YOUR_CLUSTER_ENDPOINT"

client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
})

if err != nil {
    fmt.Println(err.Error())

    // handle error
}

defer client.Close(ctx)

_, err = client.Upsert(ctx, milvusclient.NewColumnBasedInsertOption("users").

    WithInt64Column("pk", []int64{1}).

    WithColumns(column.NewColumnVarCharArray("tags", [][]string{{"new", "trial", "premium"}})).

    WithPartialUpdate(true),
)

if err != nil {
    fmt.Println(err.Error())

    // handle err
}
use milvus::v2::prelude::*;

let config = ConnectConfig::new().uri("YOUR_CLUSTER_ENDPOINT").token("YOUR_CLUSTER_TOKEN");

let client = ClientV2::new(&config).await?;

client

    .upsert(

        UpsertRequest::builder()

            .insert(

                InsertRequest::builder()

                    .collection_name("users")

                    .columns(vec![

                        FieldData::Int64 {
                            name: "pk".into(),
                            values: vec![1i64],
                        },
                        FieldData::ArrayVarChar {
                            name: "tags".into(),
                            values: vec![vec!["new".to_string(), "trial".to_string(), "premium".to_string()]],
                        },
                    ])

                    .build()?,
            )

            .partial_update(true)

            .build()?,
    )

    .await?;
#include <iostream>
#include "milvus/MilvusClientV2.h"

auto client = milvus::MilvusClientV2::Create();

milvus::ConnectParam connect_param{"YOUR_CLUSTER_ENDPOINT", "YOUR_CLUSTER_TOKEN"};

auto status = client->Connect(connect_param);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

milvus::EntityRows data = {{{"pk", 1}, {"tags", std::vector<std::string>{"new", "trial", "premium"}}}};

milvus::UpsertResponse resp_upsert;

status = client->Upsert(milvus::UpsertRequest()

                            .WithCollectionName("users")

                            .WithRowsData(std::move(data))

                            .WithPartialUpdate(true),
                        resp_upsert);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
import { MilvusClient } from "@zilliz/milvus2-sdk-node";

const address = "YOUR_CLUSTER_ENDPOINT";

const token = "YOUR_CLUSTER_TOKEN";

const client = new MilvusClient({address, token});

await client.upsert({
    collection_name: "users",
    data: [{pk: 1, tags: ["new", "trial", "premium"]}],
    partial_update: true,
});
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"

export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \

--url "${CLUSTER_ENDPOINT}/v2/vectordb/entities/upsert" \

--header "Authorization: Bearer ${TOKEN}" \

--header "Content-Type: application/json" \

--header "Request-Timeout: 10" \

-d '{
    "collectionName": "users",
    "data": [
        {"pk": 1, "tags": ["new", "trial", "premium"]}
    ],
    "partialUpdate": true
}'

# {
#     "code": 0,
#     "data": {
#         "upsertCount": 1,
#         "upsertIds": [
#             1
#         ]
#     }
# }
如果使用部分更新操作符 ARRAY_APPEND,只需发送要追加的元素:
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
from pymilvus import FieldOp

client.upsert(

    collection_name="users",
    data=[{"pk": 1, "tags": ["premium"]}],
    field_ops={"tags": FieldOp.array_append()},
)
import com.google.gson.JsonObject;
import io.milvus.v2.service.vector.request.UpsertReq;
import java.util.Collections;
import java.util.List;
import com.google.gson.Gson;

Gson gson = new Gson();

List<JsonObject> appendData = Collections.singletonList(

        gson.fromJson("{\"pk\": 1, \"tags\": [\"premium\"]}", JsonObject.class)
);

UpsertReq.FieldPartialUpdateOp appendTags = UpsertReq.FieldPartialUpdateOp.builder()

        .fieldName("tags")

        .opType(UpsertReq.FieldPartialUpdateOp.OpType.ARRAY_APPEND)

        .build();

client.upsert(UpsertReq.builder()

        .collectionName("users")


        .data(appendData)

        .fieldOps(Collections.singletonList(appendTags))


        .build());
import (
    "context"
    "fmt"

    "github.com/milvus-io/milvus/client/v3/column"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx := context.Background()

milvusAddr := "YOUR_CLUSTER_ENDPOINT"

client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
})

if err != nil {
    fmt.Println(err.Error())

    // handle error
}

defer client.Close(ctx)

_, err = client.Upsert(ctx, milvusclient.NewColumnBasedInsertOption("users").

    WithInt64Column("pk", []int64{1}).

    WithColumns(column.NewColumnVarCharArray("tags", [][]string{{"premium"}})).

    WithArrayAppend("tags"),
)

if err != nil {
    fmt.Println(err.Error())

    // handle err
}
use milvus::v2::prelude::*;

let config = ConnectConfig::new().uri("YOUR_CLUSTER_ENDPOINT").token("YOUR_CLUSTER_TOKEN");

let client = ClientV2::new(&config).await?;

client

    .upsert(

        UpsertRequest::builder()

            .insert(

                InsertRequest::builder()

                    .collection_name("users")

                    .columns(vec![

                        FieldData::Int64 {
                            name: "pk".into(),
                            values: vec![1i64],
                        },
                        FieldData::ArrayVarChar {
                            name: "tags".into(),
                            values: vec![vec!["premium".to_string()]],
                        },
                    ])

                    .build()?,
            )

            .field_ops(vec![

                FieldPartialUpdateOp::new()

                    .field_name("tags")

                    .op_type(FieldPartialUpdateOpType::ArrayAppend),
            ])

            .build()?,
    )

    .await?;
#include <iostream>
#include "milvus/MilvusClientV2.h"

auto client = milvus::MilvusClientV2::Create();

milvus::ConnectParam connect_param{"YOUR_CLUSTER_ENDPOINT", "YOUR_CLUSTER_TOKEN"};

auto status = client->Connect(connect_param);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

milvus::EntityRows data = {{{"pk", 1}, {"tags", std::vector<std::string>{"premium"}}}};

milvus::UpsertResponse resp_upsert;

status = client->Upsert(milvus::UpsertRequest()

                            .WithCollectionName("users")

                            .WithRowsData(std::move(data))

                            .AddFieldOp(milvus::FieldPartialUpdateOp("tags", milvus::FieldPartialUpdateOp::OpType::ARRAY_APPEND)),
                        resp_upsert);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
import { MilvusClient } from "@zilliz/milvus2-sdk-node";

const address = "YOUR_CLUSTER_ENDPOINT";

const token = "YOUR_CLUSTER_TOKEN";

const client = new MilvusClient({address, token});

await client.upsert({
    collection_name: "users",
    data: [{pk: 1, tags: ["premium"]}],
    field_ops: [{field_name: "tags", op: "ARRAY_APPEND"}],
});
# Note: The REST API does not expose the field_ops parameter as of v3.0.x.

# Use the gRPC SDKs to apply ARRAY_APPEND / ARRAY_REMOVE operators.
通过 field_ops 为字段指定任一操作符时,会隐式启用部分更新语义。您无需同时传入 partial_update=True。
使用限制
-
请求载荷中的值必须与目标
ARRAY字段的element_type匹配。例如,如果目标字段为ARRAY<VARCHAR>,请求载荷必须包含字符串值。 -
在当前版本中,
ARRAY_APPEND和ARRAY_REMOVE支持element_type为BOOL、INT8、INT16、INT32、INT64、FLOAT、DOUBLE或VARCHAR的ARRAY字段。 -
执行
ARRAY_APPEND后,最终数组长度不得超过该字段的max_capacity。 -
对同一 Entity 的并发 Upsert 请求不会跨请求保持原子性。如果两个请求同时更新同一个
ARRAY字段,后写入的请求可能会覆盖先写入的结果。如果您需要保留所有并发变更,请在应用层进行协调。
示例
以下示例使用一个简单的 users Collection,其中包含主键字段 pk、类型为 ARRAY<VARCHAR> 的 tags 字段,以及 embedding 向量字段。示例先插入两个带有初始 tags 值的 Entity,然后使用 ARRAY_APPEND 和 ARRAY_REMOVE 展示每个操作符如何修改已存储的数组。
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
from pymilvus import DataType, FieldOp, MilvusClient

client = MilvusClient(
    uri="YOUR_CLUSTER_ENDPOINT",
    token="YOUR_CLUSTER_TOKEN"
)

# 1. Create a collection with an ARRAY<VARCHAR> field
schema = client.create_schema(enable_dynamic_field=False)
schema.add_field("pk", DataType.INT64, is_primary=True)
schema.add_field("embedding", DataType.FLOAT_VECTOR, dim=5)
schema.add_field(
    "tags",
    DataType.ARRAY,
    element_type=DataType.VARCHAR,
    max_capacity=8,
    max_length=32,
)

index_params = client.prepare_index_params()
index_params.add_index(
    field_name="embedding",
    index_type="AUTOINDEX",
    metric_type="L2",
)

client.create_collection(
    collection_name="users",
    schema=schema,
    index_params=index_params
)

# 2. Seed two entities
client.insert(
    collection_name="users",
    data=[
        {"pk": 1, "embedding": [0.1, 0.2, 0.3, 0.4, 0.5], "tags": ["new"]},
        {"pk": 2, "embedding": [0.6, 0.7, 0.8, 0.9, 1.0], "tags": ["new", "trial"]},
    ],
)

# 3. Append tags without reading the existing ARRAY values
client.upsert(
    collection_name="users",
    data=[
        {"pk": 1, "tags": ["premium", "vip"]},
        {"pk": 2, "tags": ["premium"]},
    ],
    field_ops={"tags": FieldOp.array_append()},
)

res = client.query(
    collection_name="users",
    filter="pk in [1, 2]",
    output_fields=["pk", "tags"],
)
print(res)

# Example output:
# data: [
#   "{'pk': 1, 'tags': ['new', 'premium', 'vip']}",
#   "{'pk': 2, 'tags': ['new', 'trial', 'premium']}"
# ]

# 4. Remove matching tags without replacing the full ARRAY field
client.upsert(
    collection_name="users",
    data=[
        {"pk": 1, "tags": ["new"]},
        {"pk": 2, "tags": ["trial"]},
    ],
    field_ops={"tags": FieldOp.array_remove()},
)

res = client.query(
    collection_name="users",
    filter="pk in [1, 2]",
    output_fields=["pk", "tags"],
)
print(res)

# Example output:
# data: [
#   "{'pk': 1, 'tags': ['premium', 'vip']}",
#   "{'pk': 2, 'tags': ['new', 'premium']}"
# ]
import com.google.gson.Gson;
import com.google.gson.JsonObject;
import io.milvus.v2.client.ConnectConfig;
import io.milvus.v2.client.MilvusClientV2;
import io.milvus.v2.common.ConsistencyLevel;
import io.milvus.v2.common.DataType;
import io.milvus.v2.common.IndexParam;
import io.milvus.v2.service.collection.request.AddFieldReq;
import io.milvus.v2.service.collection.request.CreateCollectionReq;
import io.milvus.v2.service.vector.request.InsertReq;
import io.milvus.v2.service.vector.request.QueryReq;
import io.milvus.v2.service.vector.request.UpsertReq;
import io.milvus.v2.service.vector.response.QueryResp;
import java.util.Arrays;
import java.util.Collections;
import java.util.List;

MilvusClientV2 client = new MilvusClientV2(ConnectConfig.builder()
        .uri("YOUR_CLUSTER_ENDPOINT")
        .token("YOUR_CLUSTER_TOKEN")
        .build());
Gson gson = new Gson();

// 1. Create a collection with an ARRAY<VARCHAR> field
CreateCollectionReq.CollectionSchema schema = CreateCollectionReq.CollectionSchema.builder()
        .enableDynamicField(false)
        .build();

schema.addField(AddFieldReq.builder()
        .fieldName("pk")
        .dataType(DataType.Int64)
        .isPrimaryKey(true)
        .build());
schema.addField(AddFieldReq.builder()
        .fieldName("embedding")
        .dataType(DataType.FloatVector)
        .dimension(5)
        .build());
schema.addField(AddFieldReq.builder()
        .fieldName("tags")
        .dataType(DataType.Array)
        .elementType(DataType.VarChar)
        .maxCapacity(8)
        .maxLength(32)
        .build());

List<IndexParam> indexParams = Collections.singletonList(IndexParam.builder()
        .fieldName("embedding")
        .indexType(IndexParam.IndexType.AUTOINDEX)
        .metricType(IndexParam.MetricType.L2)
        .build());

client.createCollection(CreateCollectionReq.builder()
        .collectionName("users")
        .collectionSchema(schema)
        .indexParams(indexParams)
        .consistencyLevel(ConsistencyLevel.STRONG)
        .build());

// 2. Seed two entities
List<JsonObject> data = Arrays.asList(
        gson.fromJson("{\"pk\": 1, \"embedding\": [0.1, 0.2, 0.3, 0.4, 0.5], \"tags\": [\"new\"]}", JsonObject.class),
        gson.fromJson("{\"pk\": 2, \"embedding\": [0.6, 0.7, 0.8, 0.9, 1.0], \"tags\": [\"new\", \"trial\"]}", JsonObject.class)
);

client.insert(InsertReq.builder()
        .collectionName("users")
        .data(data)
        .build());

// 3. Append tags without reading the existing ARRAY values
List<JsonObject> appendData = Arrays.asList(
        gson.fromJson("{\"pk\": 1, \"tags\": [\"premium\", \"vip\"]}", JsonObject.class),
        gson.fromJson("{\"pk\": 2, \"tags\": [\"premium\"]}", JsonObject.class)
);

UpsertReq.FieldPartialUpdateOp appendTags = UpsertReq.FieldPartialUpdateOp.builder()
        .fieldName("tags")
        .opType(UpsertReq.FieldPartialUpdateOp.OpType.ARRAY_APPEND)
        .build();

client.upsert(UpsertReq.builder()
        .collectionName("users")
        .data(appendData)
        .fieldOps(Collections.singletonList(appendTags))
        .build());

QueryResp res = client.query(QueryReq.builder()
        .collectionName("users")
        .filter("pk in [1, 2]")
        .outputFields(Arrays.asList("pk", "tags"))
        .consistencyLevel(ConsistencyLevel.STRONG)
        .build());
System.out.println(res);

// Example output:
// [
//   {"pk": 1, "tags": ["new", "premium", "vip"]},
//   {"pk": 2, "tags": ["new", "trial", "premium"]}
// ]

// 4. Remove matching tags without replacing the full ARRAY field
List<JsonObject> removeData = Arrays.asList(
        gson.fromJson("{\"pk\": 1, \"tags\": [\"new\"]}", JsonObject.class),
        gson.fromJson("{\"pk\": 2, \"tags\": [\"trial\"]}", JsonObject.class)
);

UpsertReq.FieldPartialUpdateOp removeTags = UpsertReq.FieldPartialUpdateOp.builder()
        .fieldName("tags")
        .opType(UpsertReq.FieldPartialUpdateOp.OpType.ARRAY_REMOVE)
        .build();

client.upsert(UpsertReq.builder()
        .collectionName("users")
        .data(removeData)
        .fieldOps(Collections.singletonList(removeTags))
        .build());

res = client.query(QueryReq.builder()
        .collectionName("users")
        .filter("pk in [1, 2]")
        .outputFields(Arrays.asList("pk", "tags"))
        .consistencyLevel(ConsistencyLevel.STRONG)
        .build());
System.out.println(res);

// Example output:
// [
//   {"pk": 1, "tags": ["premium", "vip"]},
//   {"pk": 2, "tags": ["new", "premium"]}
// ]
import (
    "context"
    "fmt"

    "github.com/milvus-io/milvus/client/v3/column"
    "github.com/milvus-io/milvus/client/v3/entity"
    "github.com/milvus-io/milvus/client/v3/index"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx := context.Background()

milvusAddr := "YOUR_CLUSTER_ENDPOINT"

client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
})

if err != nil {
    fmt.Println(err.Error())

    // handle error
}

defer client.Close(ctx)

    // 1. Create a collection with an ARRAY<VARCHAR> field

    schema := entity.NewSchema().WithDynamicFieldEnabled(false).

        WithField(entity.NewField().WithName("pk").WithIsPrimaryKey(true).WithDataType(entity.FieldTypeInt64)).

        WithField(entity.NewField().WithName("embedding").WithDataType(entity.FieldTypeFloatVector).WithDim(5)).

        WithField(entity.NewField().WithName("tags").WithDataType(entity.FieldTypeArray).

            WithElementType(entity.FieldTypeVarChar).WithMaxCapacity(8).WithMaxLength(32))

    if err = client.CreateCollection(ctx, milvusclient.NewCreateCollectionOption("users", schema).WithIndexOptions(

        milvusclient.NewCreateIndexOption("users", "embedding", index.NewAutoIndex(entity.L2)))); err != nil {
        fmt.Println(err.Error())
        // handle error
    }

    // 2. Seed two entities

    if _, err = client.Insert(ctx, milvusclient.NewColumnBasedInsertOption("users").

        WithInt64Column("pk", []int64{1, 2}).

        WithFloatVectorColumn("embedding", 5, [][]float32{{0.1, 0.2, 0.3, 0.4, 0.5}, {0.6, 0.7, 0.8, 0.9, 1.0}}).

        WithColumns(column.NewColumnVarCharArray("tags", [][]string{{"new"}, {"new", "trial"}}))); err != nil {
        fmt.Println(err.Error())
        // handle error
    }

    // 3. Append tags without reading the existing ARRAY values

    if _, err = client.Upsert(ctx, milvusclient.NewColumnBasedInsertOption("users").

        WithInt64Column("pk", []int64{1, 2}).

        WithColumns(column.NewColumnVarCharArray("tags", [][]string{{"premium", "vip"}, {"premium"}})).

        WithArrayAppend("tags")); err != nil {
        fmt.Println(err.Error())
        // handle error
    }

    client.LoadCollection(ctx, milvusclient.NewLoadCollectionOption("users"))

    res, err := client.Query(ctx, milvusclient.NewQueryOption("users").WithFilter("pk in [1, 2]").WithOutputFields("pk", "tags"))

    if err != nil {
        fmt.Println(err.Error())

        // handle error

    }

    fmt.Println(res)

    // Example output:

    // pk 1: tags [new premium vip]

    // pk 2: tags [new trial premium]

    // 4. Remove matching tags without replacing the full ARRAY field

    if _, err = client.Upsert(ctx, milvusclient.NewColumnBasedInsertOption("users").

        WithInt64Column("pk", []int64{1, 2}).

        WithColumns(column.NewColumnVarCharArray("tags", [][]string{{"new"}, {"trial"}})).

        WithArrayRemove("tags")); err != nil {
        fmt.Println(err.Error())
        // handle error
    }

    res, err = client.Query(ctx, milvusclient.NewQueryOption("users").WithFilter("pk in [1, 2]").WithOutputFields("pk", "tags"))

    if err != nil {
        fmt.Println(err.Error())

        // handle error

    }

    fmt.Println(res)

    // Example output:

    // pk 1: tags [premium vip]

    // pk 2: tags [new premium]
use milvus::v2::prelude::*;

let config = ConnectConfig::new().uri("YOUR_CLUSTER_ENDPOINT").token("YOUR_CLUSTER_TOKEN");

let client = ClientV2::new(&config).await?;

    // 1. Create a collection with an ARRAY<VARCHAR> field

    let schema = CollectionSchema::new()

        .add_field(FieldSchema::new().name("pk").data_type(DataType::Int64).primary_key(true))

        .add_field(FieldSchema::new().name("embedding").data_type(DataType::FloatVector).dimension(5))

        .add_field(

            FieldSchema::new()

                .name("tags")

                .data_type(DataType::Array)

                .element_type(DataType::VarChar)

                .max_capacity(8)

                .max_length(32),
        );

    client

        .create_collection(

            CreateCollectionRequest::builder().collection_name("users").schema(schema).build()?,
        )

        .await?;

    client

        .create_index(

            CreateIndexRequest::builder()

                .collection_name("users")

                .index_param(

                    IndexParam::new()

                        .field_name("embedding")

                        .index_type(IndexType::AutoIndex)

                        .metric_type(MetricType::L2),
                )

                .build()?,
        )

        .await?;

    client
        .load_collection(LoadCollectionRequest::builder().collection_name("users").build()?)
        .await?;

    // 2. Seed two entities

    client

        .insert(

            InsertRequest::builder()

                .collection_name("users")

                .columns(vec![

                    FieldData::Int64 {
                        name: "pk".into(),
                        values: vec![1i64, 2],
                    },
                    FieldData::FloatVector {
                        name: "embedding".into(),
                        values: vec![vec![0.1, 0.2, 0.3, 0.4, 0.5], vec![0.6, 0.7, 0.8, 0.9, 1.0]],
                    },
                    FieldData::ArrayVarChar {
                        name: "tags".into(),
                        values: vec![vec!["new".to_string()], vec!["new".to_string(), "trial".to_string()]],
                    },
                ])

                .build()?,
        )

        .await?;

    // 3. Append tags without reading the existing ARRAY values

    client

        .upsert(

            UpsertRequest::builder()

                .insert(

                    InsertRequest::builder()

                        .collection_name("users")

                        .columns(vec![

                            FieldData::Int64 {
                                name: "pk".into(),
                                values: vec![1i64, 2],
                            },
                            FieldData::ArrayVarChar {
                                name: "tags".into(),
                                values: vec![
                                    vec!["premium".to_string(), "vip".to_string()],
                                    vec!["premium".to_string()],
                                ],
                            },
                        ])

                        .build()?,
                )

                .field_ops(vec![

                    FieldPartialUpdateOp::new()

                        .field_name("tags")

                        .op_type(FieldPartialUpdateOpType::ArrayAppend),
                ])

                .build()?,
        )

        .await?;

    let res = client

        .query(

            QueryRequest::builder()

                .collection_name("users")

                .filter("pk in [1, 2]")

                .output_fields(vec!["pk".to_string(), "tags".to_string()])

                .build()?,
        )

        .await?;

    println!("{res:?}");

    // Example output:

    // pk 1: tags [new premium vip]

    // pk 2: tags [new trial premium]

    // 4. Remove matching tags without replacing the full ARRAY field

    client

        .upsert(

            UpsertRequest::builder()

                .insert(

                    InsertRequest::builder()

                        .collection_name("users")

                        .columns(vec![

                            FieldData::Int64 {
                                name: "pk".into(),
                                values: vec![1i64, 2],
                            },
                            FieldData::ArrayVarChar {
                                name: "tags".into(),
                                values: vec![vec!["new".to_string()], vec!["trial".to_string()]],
                            },
                        ])

                        .build()?,
                )

                .field_ops(vec![

                    FieldPartialUpdateOp::new()

                        .field_name("tags")

                        .op_type(FieldPartialUpdateOpType::ArrayRemove),
                ])

                .build()?,
        )

        .await?;

    let res = client

        .query(

            QueryRequest::builder()

                .collection_name("users")

                .filter("pk in [1, 2]")

                .output_fields(vec!["pk".to_string(), "tags".to_string()])

                .build()?,
        )

        .await?;

    println!("{res:?}");

    // Example output:

    // pk 1: tags [premium vip]

    // pk 2: tags [new premium]
#include <iostream>
#include "milvus/MilvusClientV2.h"

auto client = milvus::MilvusClientV2::Create();

auto status = client->Connect(milvus::ConnectParam("YOUR_CLUSTER_ENDPOINT", "YOUR_CLUSTER_TOKEN"));

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

// 1. Create a collection with an ARRAY<VARCHAR> field

milvus::CollectionSchema schema;

schema.AddField(milvus::FieldSchema("pk", milvus::DataType::INT64, "", true, false));

schema.AddField(milvus::FieldSchema("embedding", milvus::DataType::FLOAT_VECTOR).WithDimension(5));

schema.AddField(milvus::FieldSchema("tags", milvus::DataType::ARRAY).WithElementType(milvus::DataType::VARCHAR).WithMaxCapacity(8).WithMaxLength(32));

status = client->CreateCollection(milvus::CreateCollectionRequest().WithCollectionName("users").WithCollectionSchema(std::make_shared<milvus::CollectionSchema>(schema)));

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

status = client->CreateIndex(milvus::CreateIndexRequest().WithCollectionName("users").AddIndex(milvus::IndexDesc("embedding", "", milvus::IndexType::AUTOINDEX, milvus::MetricType::L2)));

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

status = client->LoadCollection(milvus::LoadCollectionRequest().WithCollectionName("users"));
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

// 2. Seed two entities

milvus::EntityRows seed = {
    {{"pk", 1}, {"embedding", std::vector<float>{0.1, 0.2, 0.3, 0.4, 0.5}}, {"tags", std::vector<std::string>{"new"}}},
    {{"pk", 2}, {"embedding", std::vector<float>{0.6, 0.7, 0.8, 0.9, 1.0}}, {"tags", std::vector<std::string>{"new", "trial"}}},
};

milvus::InsertResponse insert_resp;

status = client->Insert(milvus::InsertRequest().WithCollectionName("users").WithRowsData(std::move(seed)), insert_resp);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

// 3. Append tags without reading the existing ARRAY values

milvus::EntityRows append_data = {
    {{"pk", 1}, {"tags", std::vector<std::string>{"premium", "vip"}}},
    {{"pk", 2}, {"tags", std::vector<std::string>{"premium"}}},
};

milvus::UpsertResponse resp_upsert;

status = client->Upsert(milvus::UpsertRequest().WithCollectionName("users").WithRowsData(std::move(append_data))

                            .AddFieldOp(milvus::FieldPartialUpdateOp("tags", milvus::FieldPartialUpdateOp::OpType::ARRAY_APPEND)),
                        resp_upsert);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

// 4. Remove matching tags without replacing the full ARRAY field

milvus::EntityRows remove_data = {
    {{"pk", 1}, {"tags", std::vector<std::string>{"new"}}},
    {{"pk", 2}, {"tags", std::vector<std::string>{"trial"}}},
};

status = client->Upsert(milvus::UpsertRequest().WithCollectionName("users").WithRowsData(std::move(remove_data))

                            .AddFieldOp(milvus::FieldPartialUpdateOp("tags", milvus::FieldPartialUpdateOp::OpType::ARRAY_REMOVE)),
                        resp_upsert);

if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
import { MilvusClient, DataType } from "@zilliz/milvus2-sdk-node";

const client = new MilvusClient({ address: "YOUR_CLUSTER_ENDPOINT", token: "YOUR_CLUSTER_TOKEN" });

// 1. Create a collection with an ARRAY<VARCHAR> field

await client.createCollection({
    collection_name: "users",
    schema: [
        { name: "pk", data_type: DataType.Int64, is_primary_key: true },
        { name: "embedding", data_type: DataType.FloatVector, dim: 5 },
        { name: "tags", data_type: DataType.Array, element_type: DataType.VarChar, max_capacity: 8, max_length: 32 },
    ],
    index_params: [{ field_name: "embedding", index_type: "AUTOINDEX", metric_type: "L2" }],
});

// 2. Seed two entities

await client.insert({
    collection_name: "users",
    data: [
        { pk: 1, embedding: [0.1, 0.2, 0.3, 0.4, 0.5], tags: ["new"] },
        { pk: 2, embedding: [0.6, 0.7, 0.8, 0.9, 1.0], tags: ["new", "trial"] },
    ],
});

// 3. Append tags without reading the existing ARRAY values

await client.upsert({
    collection_name: "users",
    data: [
        { pk: 1, tags: ["premium", "vip"] },
        { pk: 2, tags: ["premium"] },
    ],
    field_ops: [{ field_name: "tags", op: "ARRAY_APPEND" }],
});

let res = await client.query({ collection_name: "users", filter: "pk in [1, 2]", output_fields: ["pk", "tags"] });

console.log(res.data);

// Example output:

// [{ pk: 1, tags: ['new', 'premium', 'vip'] },
//  { pk: 2, tags: ['new', 'trial', 'premium'] }]

// 4. Remove matching tags without replacing the full ARRAY field

await client.upsert({
    collection_name: "users",
    data: [
        { pk: 1, tags: ["new"] },
        { pk: 2, tags: ["trial"] },
    ],
    field_ops: [{ field_name: "tags", op: "ARRAY_REMOVE" }],
});

res = await client.query({ collection_name: "users", filter: "pk in [1, 2]", output_fields: ["pk", "tags"] });

console.log(res.data);

// Example output:

// [{ pk: 1, tags: ['premium', 'vip'] },
//  { pk: 2, tags: ['new', 'premium'] }]
# Note: The REST API does not expose the field_ops parameter as of v3.0.x.

# ARRAY_APPEND / ARRAY_REMOVE operators are available via the gRPC SDKs only.